
Custom AI Model Deployment on AWS for Wealth Advisory
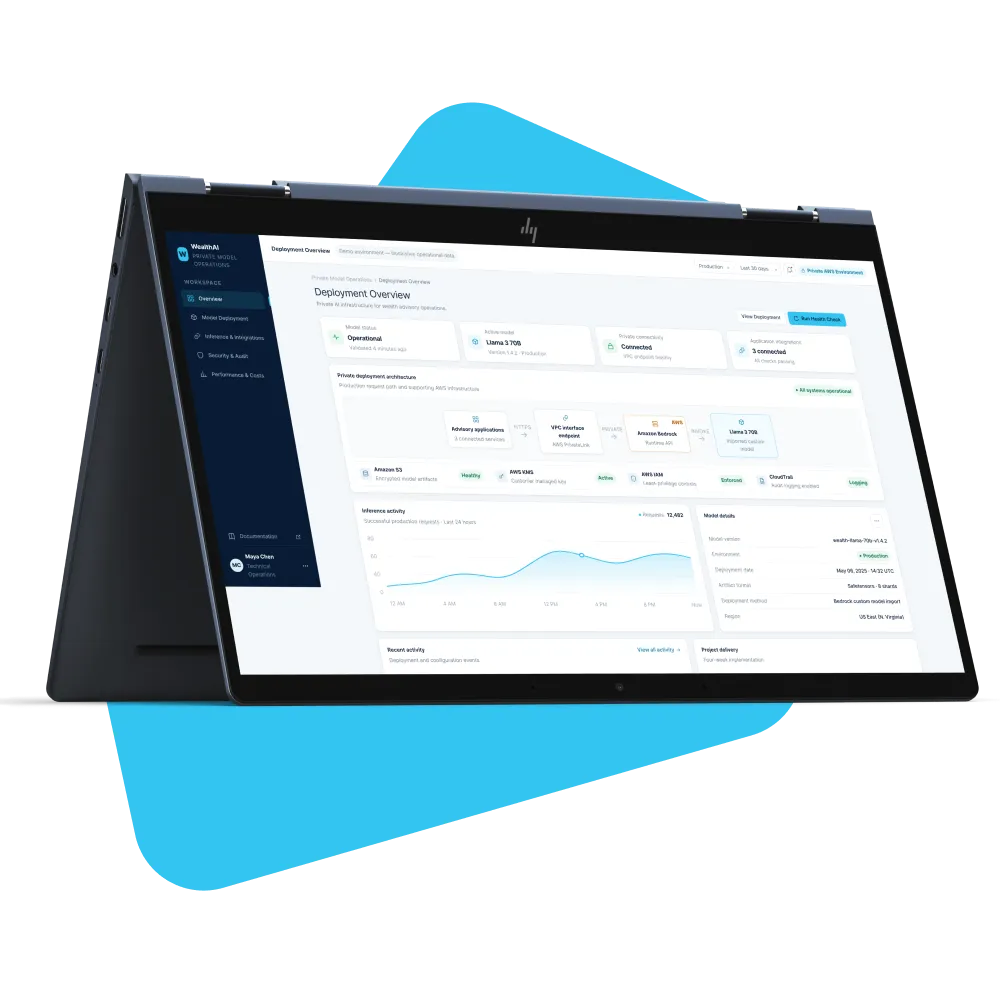
Creole Studios helped a US-based wealth management firm deploy its fine-tuned Llama 3 70B model on Amazon Bedrock, enabling secure financial analysis and compliance workflows through managed AI infrastructure, private connectivity, and seamless application integration without complex GPU management.
 United States
18K–19.5K USD
4 Weeks
AWS Cloud / Amazon Bedrock
About the Project
Bringing Private Generative AI Into Wealth Management Operations
A US-based wealth management advisory firm developed a proprietary, fine-tuned Llama 3 70B model to support portfolio analysis, financial document reviews, and regulatory compliance workflows. However, deploying such a large model required secure infrastructure, reliable inference performance, and complex GPU management. Creole Studios helped the firm prepare and deploy its custom AI model on Amazon Bedrock, establishing a secure, managed AWS environment integrated with its existing advisory applications.

Project Challenges
Moving a proprietary financial AI model into production required more than configuring an inference endpoint. The deployment needed to address model compatibility, infrastructure management, performance, security, and financial-sector operational requirements.


Deploying a Fine-Tuned 70B Model: The fine-tuned Llama 3 70B model required weight validation, LoRA adapter merging, and compatible packaging to meet Bedrock’s import standards without losing financial domain accuracy.
Eliminating GPU Infrastructure Overhead: Without an in-house MLOps team, the client needed to avoid managing complex GPU servers, custom serving stacks, and continuous hardware maintenance.
Ensuring Peak-Hour Inference Reliability: High trading volumes and concurrent portfolio analyses required low-latency, uninterrupted model availability during peak market hours.
Securing Sensitive Financial Data: Protecting proprietary portfolios and client records demanded private AWS networking, end-to-end encryption, and granular access controls.
Meeting Strict Financial Compliance: The deployment had to satisfy SEC and FINRA standards through strict access policies, KMS-level encryption, and tamper-proof audit logging.
Controlling Ongoing Cloud Costs: The client required a cost-efficient deployment model that eliminated dedicated GPU waste while sustaining enterprise advisory workloads.


How Did We Help?
Creole Studios implemented a phased AI model deployment approach, covering model assessment, Amazon Bedrock deployment, security configuration, application integration, and production validation.
Model Assessment & Deployment Planning
Model Preparation & Artifact Validation
Amazon Bedrock Model Deployment
Private Networking & Security Configuration
Application Integration & Inference Validation
Production Testing & Deployment Handover
Production Monitoring & Performance Optimization

The outcome
Creole Studios successfully deployed the client’s fine-tuned Llama 3 70B model on Amazon Bedrock within 4 weeks, enabling secure AI inference through private AWS connectivity, IAM controls, and encryption. The deployment eliminated direct GPU infrastructure management, integrated seamlessly with existing advisory applications, and achieved a reported 55% reduction in total cost of ownership and 42 ms p95 serving latency, supporting efficient financial analysis and compliance workflows.

Williams
"Creole Studios helped us deploy our custom AI model on AWS without the complexity of managing GPU infrastructure internally. Their team understood our security, performance, and compliance requirements and delivered a reliable solution within a short timeline. The deployment has significantly simplified our AI operations while giving us the performance and control our financial workflows require."